Research
My research focuses on scalable and adaptive learning for optimization and discovery: building models and decision rules that use limited data and computation effectively.
How can a learning system use limited data and computation effectively when its modeling assumptions may need to change?
I study this question through inductive bias, the assumptions that make some patterns easier to learn than others. A kernel determines how observations inform predictions at unseen inputs, which relationships the model favors, and how uncertainty guides the next experiment. My work makes these choices more affordable to learn, adaptable to the task, and open to discovery.
Scalable learning
Useful models must be affordable to train. My grid spectral mixture kernels use structured representations for multidimensional covariance. SLIM-KL exploits sparse kernel weights to distribute fitting and reduce communication while keeping raw data local. ZAP estimates a full hyperparameter gradient from two loss evaluations per iteration, making updates practical when direct gradients are expensive or unavailable.
The same interest in computational structure extends beyond kernels. FedMAvg combines alternating minimization and model averaging for communication-efficient federated matrix factorization. MIMOMamba uses structured state-space dynamics to capture interactions across channels while limiting parameter and computation costs.
-
Gaussian Process Regression with Grid Spectral Mixture Kernel: Distributed Learning for Multidimensional Data
25th International Conference on Information Fusion (FUSION), 2022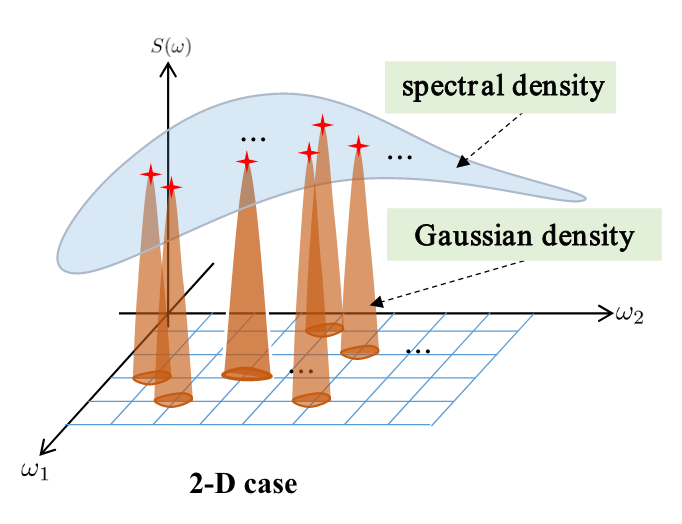
TL;DR
We introduce a grid spectral mixture kernel for multidimensional Gaussian processes and train it with distributed ADMM, so agents fit the kernel without sharing raw data.
Abstract
Kernel design for Gaussian processes (GPs) along with the associated hyper-parameter optimization is a challenging problem. In this paper, we propose a novel grid spectral mixture (GSM) kernel design for GPs that can automatically fit multidimensional data with affordable model complexity and superior modeling capability. To alleviate the computational complexity due to the curse of dimensionality, we leverage a multicore computing environment to optimize the kernel hyper-parameters in a distributed manner. We further propose a doubly distributed learning algorithm based on the alternating direction method of multipliers (ADMM) which enables multiple agents to learn the kernel hyper-parameters collaboratively. The doubly distributed learning algorithm is shown to be effective in reducing the overall computational complexity while preserving data privacy during the learning process. Experiments on various one-dimensional and multidimensional data sets demonstrate that the proposed kernel design yields superior training and prediction performance compared to its competitors.
Open Question
The grid spectral mixture kernel fits multidimensional data with fewer hyperparameters than a naive product of mixtures, which is a strong inductive bias if the spectrum really lives on that discrete lattice. Deriving why that structure is the right one, and when it approximates the covariance rather than merely interpolating it, remains open.
@inproceedings{suwandi2022gaussian,
  title = {Gaussian Process Regression with Grid Spectral Mixture Kernel: Distributed Learning for Multidimensional Data},
  author = {Suwandi, Richard Cornelius and Lin, Zhidi and Sun, Yiyong and Wang, Zhiguo and Cheng, Lei and Yin, Feng},
  booktitle = {25th International Conference on Information Fusion (FUSION)},
  pages = {1--8},
  year = {2022},
  organization = {IEEE},
}
-
Sparsity-Aware Distributed Learning for Gaussian Processes with Linear Multiple Kernel
IEEE Transactions on Neural Networks and Learning Systems, 2025TL;DR
Hyperparameters of the GSM kernel come out sparse. SLIM-KL uses that sparsity, plus quantized ADMM, so many agents can train a large GP kernel privately and with less communication.
Abstract
Gaussian processes (GPs) stand as crucial tools in machine learning and signal processing, with their effectiveness hinging on kernel design and hyper-parameter optimization. This paper presents a novel GP linear multiple kernel (LMK) and a generic sparsity-aware distributed learning framework to optimize the hyper-parameters. The newly proposed grid spectral mixture (GSM) kernel is tailored for multi-dimensional data, effectively reducing the number of hyper-parameters while maintaining good approximation capabilities. We further demonstrate that the associated hyper-parameter optimization of this kernel yields sparse solutions. To exploit the inherent sparsity property of the solutions, we introduce the Sparse LInear Multiple Kernel Learning (SLIM-KL) framework. The framework incorporates a quantized alternating direction method of multipliers (ADMM) scheme for collaborative learning among multiple agents, where the local optimization problem is solved using a distributed successive convex approximation (DSCA) algorithm. SLIM-KL effectively manages large-scale hyper-parameter optimization for the proposed kernel, simultaneously ensuring data privacy and minimizing communication costs. Theoretical analysis establishes convergence guarantees for the learning framework, while experiments on diverse datasets demonstrate the superior prediction performance and efficiency of our proposed methods.
Open Question
Hyperparameter optimization for this kernel yields sparse weights, which quantized ADMM then exploits, shrinking communication and, in principle, the model class the predictor uses. Deriving whether those zeros improve prediction, or mainly cut communication while leaving the same function class, remains open.
@article{suwandi2023gaussian,
  title = {Sparsity-Aware Distributed Learning for Gaussian Processes with Linear Multiple Kernel},
  author = {Suwandi, Richard Cornelius and Lin, Zhidi and Yin, Feng and Wang, Zhiguo and Theodoridis, Sergios},
  journal = {IEEE Transactions on Neural Networks and Learning Systems},
  year = {2025},
}
-
Breaking the Curse of Dimensionality in Gaussian Process Training With Zeroth-Order Adaptive Perturbation
ORAL 51th IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), 2026TL;DR
Training a Gaussian process gets expensive as the number of hyperparameters grows. ZAP estimates the full gradient from two loss evaluations, independent of dimension, with about 20x lower error and 118x less optimization time.
Abstract
Hyperparameter optimization remains a core challenge in training Gaussian processes (GPs), primarily due to the high computational cost and numerical instabilities associated with gradient-based optimizers. These issues are exacerbated in high-dimensional spaces, where the optimization landscapes become increasingly complex and difficult to navigate efficiently. We propose zeroth-order adaptive perturbation (ZAP), a scalable gradient-free algorithm that leverages simultaneous perturbations sampled from a Bernoulli distribution to obtain accurate gradient estimates with only two function evaluations per iteration, regardless of the hyperparameter dimensionality. Our theoretical analysis establishes that the gradient estimator is asymptotically unbiased and that ZAP converges to a stationary point under standard assumptions. Empirically, ZAP outperforms state-of-the-art gradient-based and gradient-free baselines on real-world datasets, achieving an average of 20 times reduction in mean-squared-error and a 118 times speedup in optimization time.
Open Question
Two simultaneous Bernoulli probes recover the full hyperparameter gradient from two loss evaluations, independent of how many kernel parameters there are, whereas finite differences would need two evaluations per parameter. ZAP shows that this two-point estimator is asymptotically unbiased and that the iterates reach a stationary point of the GP marginal likelihood, so deriving a finite-sample error bound for the estimator, and a convergence rate for the hyperparameters, remains open.
@inproceedings{suwandi2026breaking,
  title = {Breaking the Curse of Dimensionality in Gaussian Process Training With Zeroth-Order Adaptive Perturbation},
  author = {Suwandi, Richard Cornelius and Yin, Feng and Chang, Tsung-Hui},
  booktitle = {51th IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP)},
  year = {2026},
  organization = {IEEE},
}
-
Demystifying Model Averaging for Communication-Efficient Federated Matrix Factorization
46th IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), 2021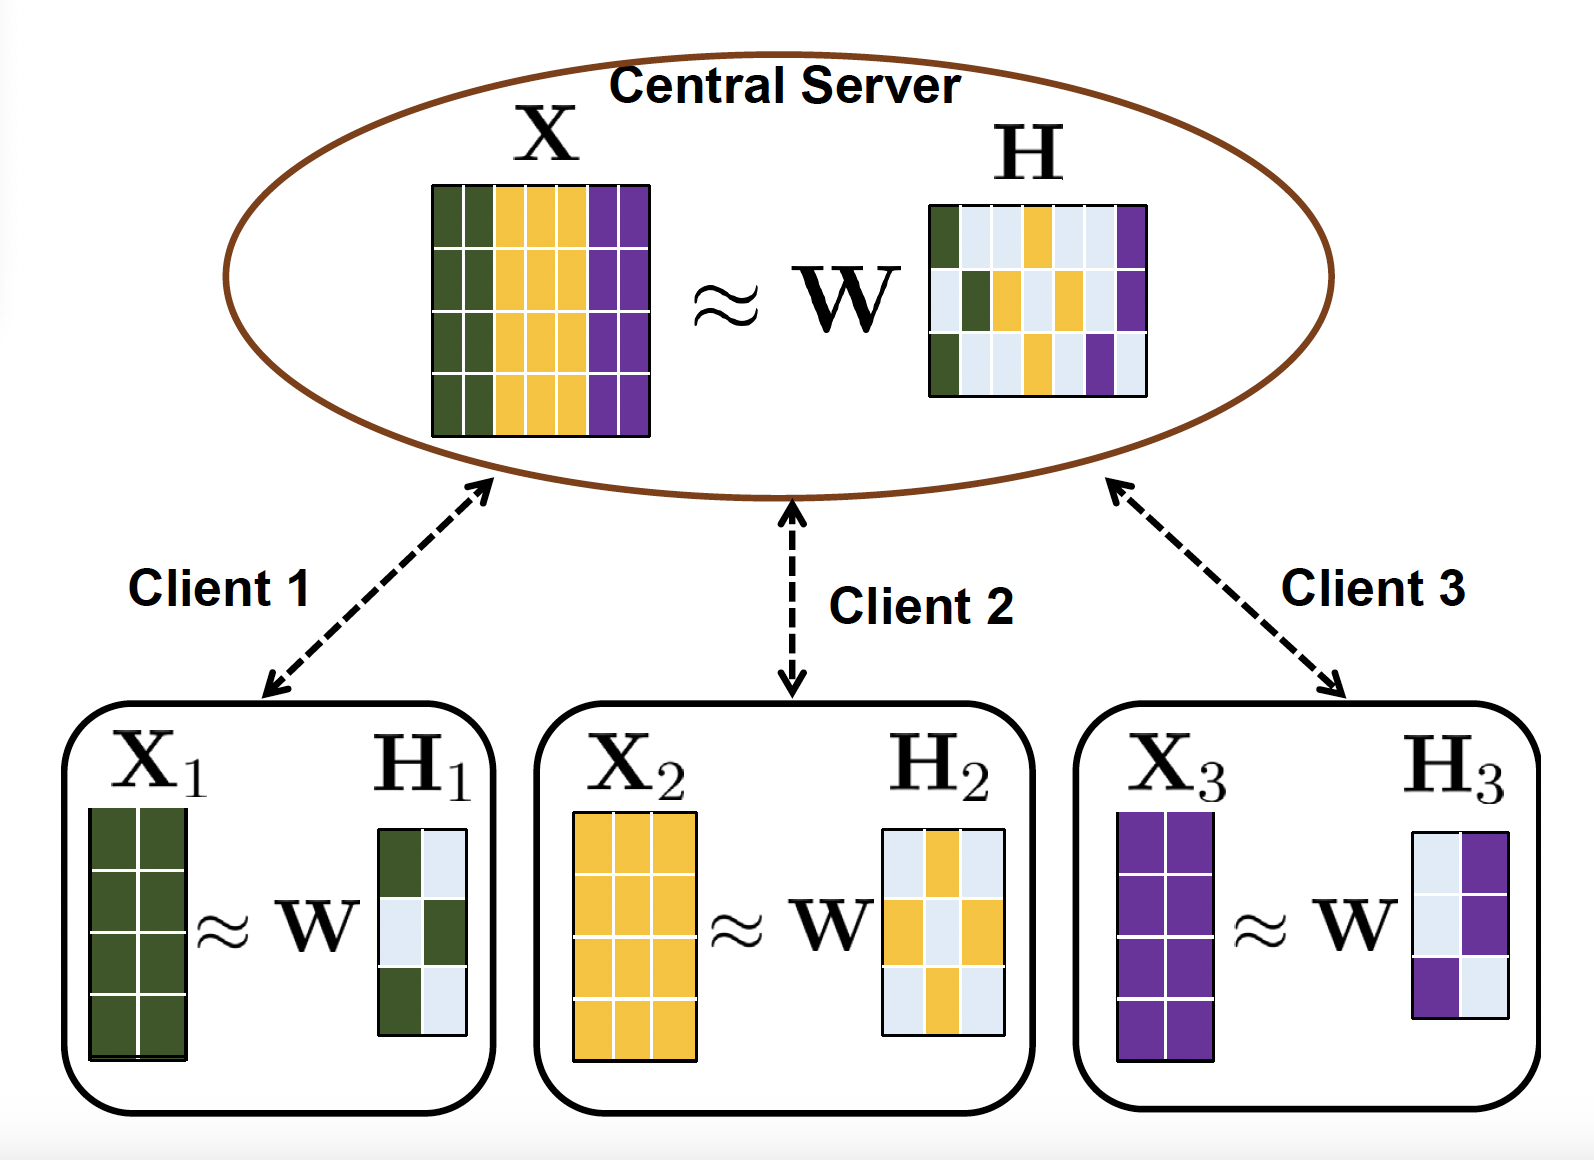
TL;DR
Model averaging had not been applied to federated matrix factorization. FedMAvg combines alternating minimization with averaging, and communicating less often with fewer clients cuts cost on heterogeneous data.
Abstract
Federated learning (FL) is encountered with the challenge of training a model in massive and heterogeneous networks. Model averaging (MA) has become a popular FL paradigm where parallel (stochastic) gradient descent (GD) is run on a small sampled subset of clients multiple times before uploading the local models to a server for averaging, which has been proven effective in reducing the communication cost for achieving a good model. However, MA has not been considered for the important matrix factorization (MF) model, which has vast signal processing and machine learning applications. In this paper, we investigate the federated MF problem and propose a new MA based algorithm, named FedMAvg, by judiciously combining the alternating minimization technique and MA. Through analysis, we show that gradually decreasing the number of local GD and only allowing partial clients to communicate with the server can greatly reduce the communication cost, especially in heterogeneous networks with non-i.i.d. data. Experimental results by applying FedMAvg to data clustering and item recommendation tasks demonstrate its efficacy in terms of both task performance and communication efficiency.
Open Question
Fewer local steps and fewer participating clients cut communication on heterogeneous matrix factorization, yet the factorization still improves even though sampling clients looks like it should add noise. Deriving when partial participation speeds the global factorization, rather than slowing it, remains open.
@inproceedings{wang2021demystifying,
  title = {Demystifying Model Averaging for Communication-Efficient Federated Matrix Factorization},
  author = {Wang, Shuai and Suwandi, Richard Cornelius and Chang, Tsung-Hui},
  booktitle = {46th IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP)},
  pages = {3680--3684},
  year = {2021},
  organization = {IEEE},
}
-
MIMOMamba: From Scalar Duality to Matrix-Valued Attention
43rd International Conference on Machine Learning (ICML), 2026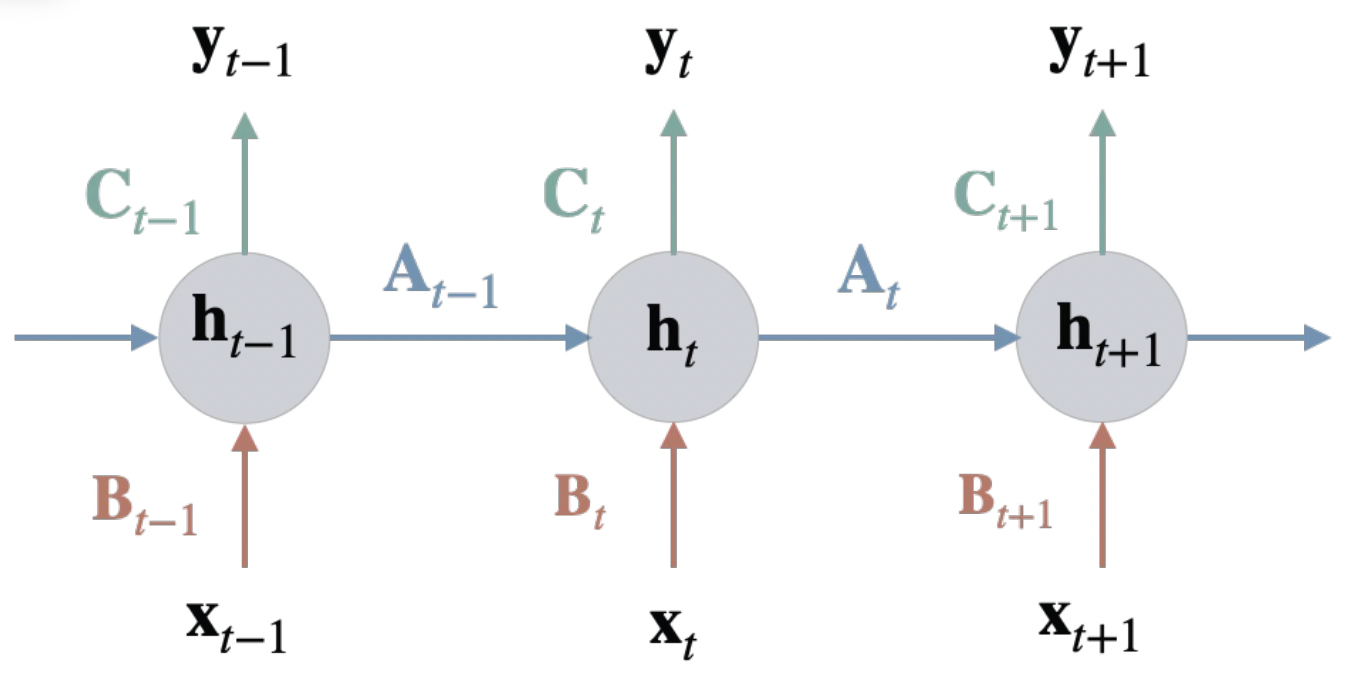
TL;DR
Mamba’s state-space duality is limited to single-input systems, so dimensions cannot mix inside the state. MIMOMamba extends it to MIMO with a matrix polynomial, matching or beating Transformers at about one-third the parameters.
Abstract
The state space duality (SSD) framework, central to modern state-space models (SSMs) such as Mamba, has established an efficient attention-like mechanism by leveraging the commutative property of linear recurrences. However, existing formulations are limited to single-input single-output (SISO) systems that enforce commutativity with a restrictive scalar-identity constraint, which prevents cross-dimensional interactions within the state dynamics. In this work, we generalize SSD to the MIMO setting by introducing a matrix polynomial parameterization. This approach not only provides a principled way to ensure commutativity for generalized duality but also induces a shared algebraic structure across state transitions, thereby significantly reducing parameter redundancy. Building on this foundation, we present MIMOMamba, a multi-head SSM architecture that captures rich cross-dimensional dynamics while retaining linear-time training. Empirical results on a sequence modeling benchmark show that MIMOMamba matches or exceeds the performance of standard Transformers with only approximately one-third the parameters of the baseline.
Open Question
A matrix polynomial restores the commutativity that scalar Mamba gets from an identity constraint, so channels can mix inside the state instead of staying decoupled. Deriving which cross-channel mixing patterns that algebra can express, and which still need attention, remains open.
@article{li2026mimomamba,
  title = {MIMOMamba: From Scalar Duality to Matrix-Valued Attention},
  author = {Li, Yanbo and Suwandi, Richard Cornelius and Yin, Feng and Sun, Yiyong and Huang, Wei and Pu, Wenqiang},
  journal = {43rd International Conference on Machine Learning (ICML)},
  year = {2026},
  organization = {ICML},
}

Adaptive optimization
When evaluations are expensive, uncertainty should help decide where to spend them. GRAPE refines a local gradient posterior, then chooses a direction using expected progress conditional on descent. Q-exponential Bayesian optimization changes predictive tail shape while retaining tractable acquisition calculations. These methods address different parts of the decision process: allocating queries and adapting the predictive assumptions behind them.
In ongoing work on Multiverse Bayesian Optimization (MvBO), I study how a finite representation budget should be shared across complementary kernels whose features are fitted jointly. The question is which useful directions survive that budget and how the omitted structure affects optimization.
-
GRAPE: Gradient Refinement and Progress-Aware Exploitation for Query-Efficient High-Dimensional Bayesian Optimization
PREPRINT 2026TL;DR
Local Bayesian optimization often takes tiny steps that are almost sure to descend. GRAPE first sharpens the local gradient, then moves in the direction with the largest expected decrease, giving a 5.4x speedup on adversarial attacks and 3.8 log-units better regret on LLM prompt optimization.
Abstract
Optimizing expensive, high-dimensional black-box functions remains a central challenge in modern machine learning and scientific discovery. While local Bayesian optimization mitigates the curse of dimensionality, existing techniques often prioritize the probability of descent over the magnitude of progress. This leads to overly conservative steps that yield negligible improvement, wasting queries on directions that are nearly certain to descend but offer little decrease. We introduce Gradient Refinement and Progress-Aware Exploitation (GRAPE), a two-stage framework that first sharpens the local gradient posterior via a closed-form acquisition function, then selects update directions by maximizing the expected decrease conditional on descent. Theoretical analysis proves that this gradient refinement stage monotonically minimizes local uncertainty and that the progress-aware direction converges to true steepest descent as the posterior sharpens. Empirically, GRAPE demonstrates superior query efficiency across high-dimensional tasks: in black-box adversarial attacks, it achieves an average 5.4× speedup over baselines, and on large language model prompt optimization tasks, it outperforms the second best method by a reduction of 3.8 log-units in the final average regret.
Open Question
Local BO often takes steps that are almost sure to descend even when the drop is tiny, so GRAPE first sharpens the local gradient and then moves in the direction with the largest expected decrease. Classical analyses track the chance of descent, so deriving how fast those sharpened steps compound, and a rate of convergence for the overall search, remains open.
@misc{suwandi-grape,
  title = {GRAPE: Gradient Refinement and Progress-Aware Exploitation for Query-Efficient High-Dimensional Bayesian Optimization},
  author = {Suwandi, Richard Cornelius and Yin, Feng},
  year = {2026},
  publisher = {arXiv},
}

-
TL;DR
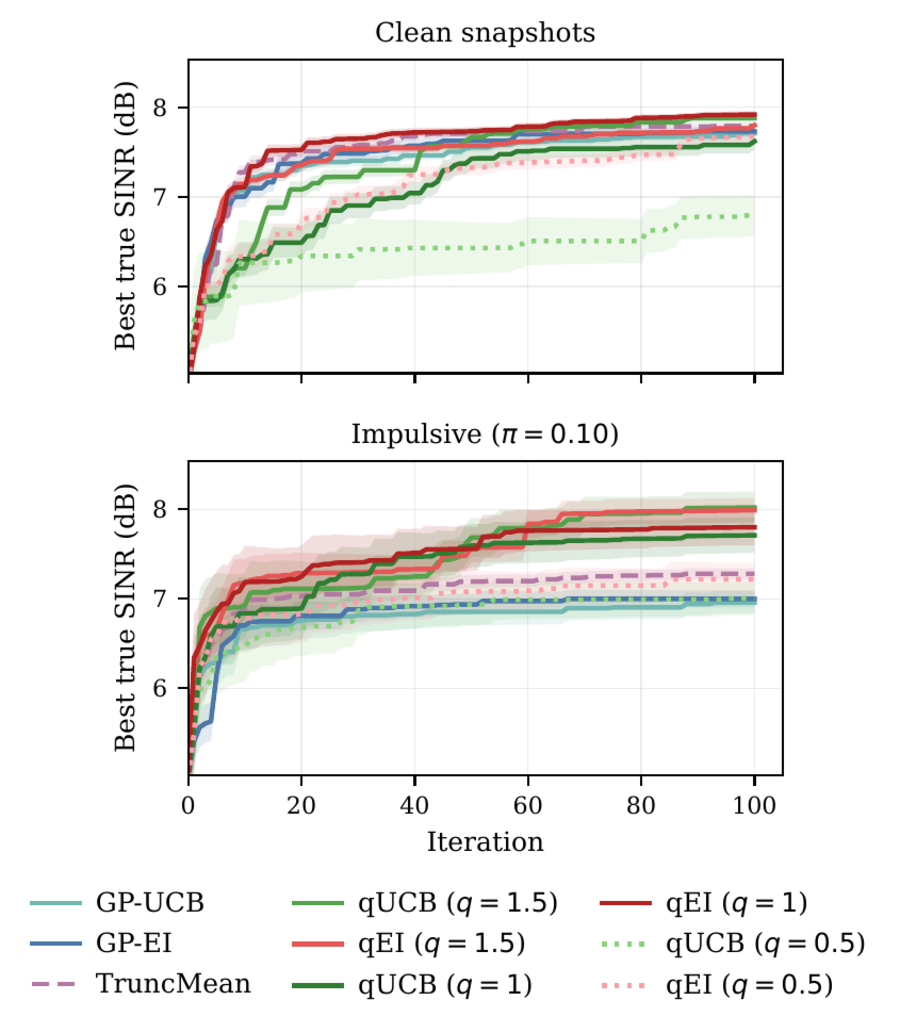
Standard Bayesian optimization is brittle when a single corrupted evaluation can shift the Gaussian process posterior and send the search the wrong way. q-ED-BO keeps that posterior’s closed-form mean and variance, and replaces the Gaussian predictive with a q-exponential whose shape q sets the tail, recovering the GP at q = 2. On beamformer and adaptive-filter tuning it matches the baselines on clean data, and under impulsive outliers it improves the strongest baseline by about 0.7 dB in output SINR and 1.1 to 1.2 dB in misalignment reduction.
Abstract
Bayesian optimization (BO) is a widely used framework for optimizing expensive black-box objectives, but standard BO methods often use Gaussian process (GP) surrogates whose Gaussian assumption is sensitive to outliers and heavy-tailed noise. We introduce q-ED-BO, a robust BO method whose surrogate follows a univariate q-exponential (q-ED) distribution, preserving GP-BO’s closed-form posterior mean and variance while a shape parameter q controls the tail behavior, recovering the GP at q = 2 and growing heavier-tailed with wider confidence bounds as q decreases. This tractability yields a closed-form q-upper confidence bound (q-UCB) with sublinear regret, and an exact closed-form q-expected improvement (q-EI) that generalizes EI to the heavy-tailed predictive, recovering classical EI at q = 2. Experiments on beamformer and adaptive filter tuning with impulsive outliers show that q-ED-BO matches or exceeds existing baselines on clean data, and under corruption, improves the strongest baseline by approximately 0.7 dB in output SINR and 1.1 to 1.2 dB in misalignment reduction.
Open Question
The shape q is fixed before the search, and q-EI is available in closed form but has no regret guarantee, so learning q from the data, and a convergence rate for q-EI, remain open.
@misc{suwandi2026qed,
  title = {Robust Bayesian Optimization with Q-Exponential Surrogates},
  author = {Suwandi, Richard Cornelius and Lin, Zhidi and Yin, Feng and Zoubir, Abdelhak M.},
  year = {2026},
  publisher = {arXiv},
}
Model structure and discovery
A useful modeling assumption may never be considered if it is difficult to express or find. CAKE makes kernel structure part of the optimization loop: a language model proposes and revises kernel compositions using task context and accumulated observations. Candidates are ranked through both statistical fit and the utility of the experiments they recommend.
My ongoing work on Kernel Autoresearch (Kernaut) extends this search to executable features and input transformations assembled through trusted kernel constructions. I analyze what the resulting representations preserve, which relationships they favor, and whether they transfer to tasks withheld from search. The aim is to discover useful inductive biases and explain why they help.
-
Adaptive Kernel Design for Bayesian Optimization Is a Piece of CAKE with LLMs
39th Conference on Neural Information Processing Systems (NeurIPS), 2025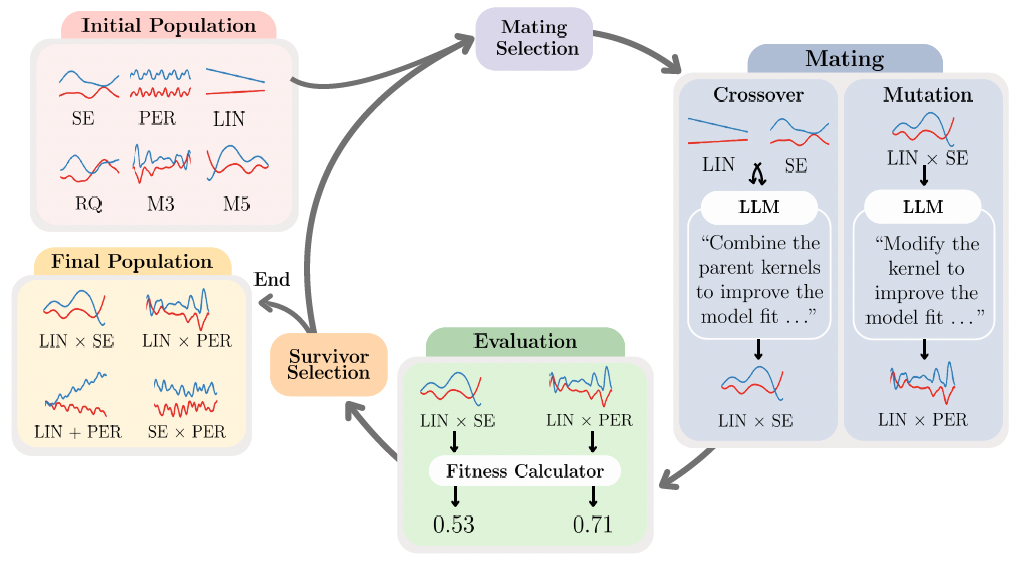
TL;DR
A poorly chosen GP kernel slows Bayesian optimization. CAKE uses an LLM to evolve kernels during the search, and BAKER picks which one to query next, improving hyperparameter optimization, controller tuning, and photonic chip design.
Abstract
The efficiency of Bayesian optimization (BO) relies heavily on the choice of the Gaussian process (GP) kernel, which plays a central role in balancing exploration and exploitation under limited evaluation budgets. Traditional BO methods often rely on fixed or heuristic kernel selection strategies, which can result in slow convergence or suboptimal solutions when the chosen kernel is poorly suited to the underlying objective function. To address this limitation, we propose a freshly-baked Context-Aware Kernel Evolution (CAKE) to enhance BO with large language models (LLMs). Concretely, CAKE leverages LLMs as the crossover and mutation operators to adaptively generate and refine GP kernels based on the observed data throughout the optimization process. To maximize the power of CAKE, we further propose BIC-Acquisition Kernel Ranking (BAKER) to select the most effective kernel through balancing the model fit measured by the Bayesian information criterion (BIC) with the expected improvement at each iteration of BO. Extensive experiments demonstrate that our fresh CAKE-based BO method consistently outperforms established baselines across a range of real-world tasks, including hyperparameter optimization, controller tuning, and photonic chip design. Our code is publicly available at https://github.com/richardcsuwandi/cake.
Open Question
CAKE adaptively rewrites the kernel during the search, so the surrogate itself changes as data arrive. Classical regret analysis assumes a fixed function class, so deriving bounds when the kernel evolves every round remains open.
@article{suwandi2025cake,
  title = {Adaptive Kernel Design for Bayesian Optimization Is a Piece of CAKE with LLMs},
  author = {Suwandi, Richard Cornelius and Yin, Feng and Wang, Juntao and Li, Renjie and Chang, Tsung-Hui and Theodoridis, Sergios},
  journal = {39th Conference on Neural Information Processing Systems (NeurIPS)},
  year = {2025},
}

Across these areas, I combine algorithm design, mathematical analysis, and empirical evaluation to make learning and optimization more effective under practical constraints. If this overlaps with your interests, email me!